Can you run Jev offline?
short answer: jev itself, no, it only runs on TypeSafe's servers. but if your app keeps asking jev the same kind of question, you can train a tiny model on those requests and run that at home. I did it with Home Assistant's assistant and the whole thing cost $0.12.
the setup
HA-Jev makes jev the brain of Home Assistant's assistant: whatever you type or say to it goes to jev as text. each command turns into one request with what you said, a snapshot of your devices, and about a dozen typed questions: what should happen (turn_on, turn_off, set_brightness…), which device, is there a delay in it, and so on. jev answers and home assistant does the thing.
it works really well. the catch is every "turn off the kitchen lights" is a trip to the internet (the HA-Jev README measures 250 to 580 ms warm and 700 to 900 after idling), and when the wifi goes down so does your assistant. people keep asking on the HA forum and HN whether it can run locally, which is what got me doing this.
quick note on voice: jev only ever sees text. in HA the voice part is separate steps around it (wake word, speech-to-text, then the agent, then text-to-speech). I typed my commands into the Assist box for this. if you want the whole voice loop offline too, HA runs speech-to-text and text-to-speech locally with its Whisper and Piper add-ons. I haven't set those up for this post.
you need: Home Assistant with HA-Jev, a free dopp.sh account, and any machine that can run Python for the last step (the HA box is fine).
1. swap one url
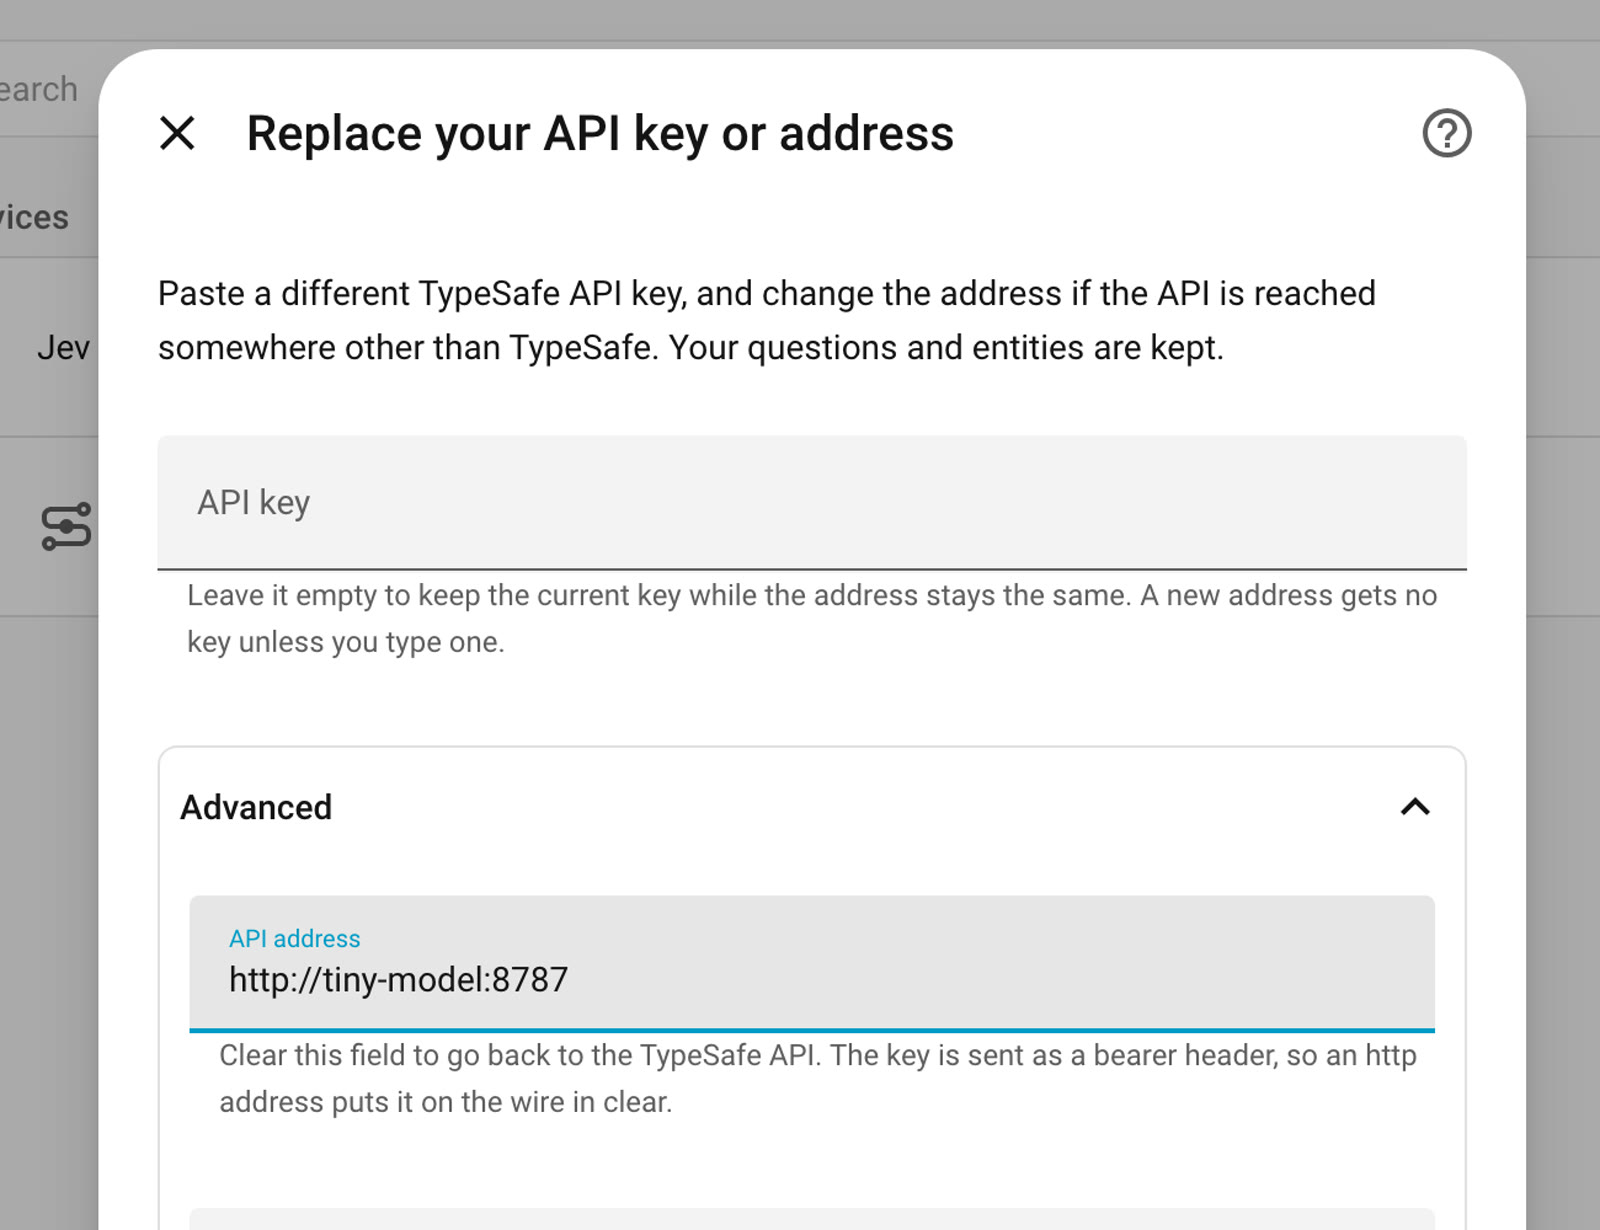
HA-Jev has an address field under Advanced. I put https://dopp.sh in it and a dopp key in the key field. jev still answers every command, dopp just keeps a copy of each request.
then I just used it for a minute. every command shows up in the request log with who answered and how long it took (jev took around 70 to 130 ms on top of the trip there).
2. is that enough to train on? no lol
the route page has an "Enough examples?" meter that counts labelled examples for every possible answer of every question. green is 20+, amber is 5 to 19, red is under 5. after four commands it was all red, 0 answers ready and 17 under 5, which is fair, nobody says "turn off the living room fan" twenty times on day one.

3. fill the gaps
two buttons on the same page.
a public dataset. Find datasets takes a Hugging Face name. Amazon's MASSIVE (SetFit/amazon_massive_intent_en-US) is 11,514 English commands real people said to voice assistants, and I added 150 of them. the meter went to 15 ready and 10 under 5. most of MASSIVE is alarms, music and the weather though, so it mostly taught the model what "not about my house" sounds like and the device stuff stayed thin.
Generate. every thin answer gets a "Write 20" button. it writes new commands aimed at that answer using the devices you actually have ("shut that window in the kitchen", "switch off the ceiling fan") and drops each one into a real request, so the device list and questions look exactly like what HA sends. I did four rounds, about 16 seconds each, for a fifth of a cent total.
after that: 23 answers ready, 16 thin, 0 under 5. turn_on had 53 examples, turn_off 26, set_brightness 15.

4. train the small one
"Which base to train" asks where the model is going to run. pick "Downloaded, offline" and it suggests Tiny, a 34 MB model (bge-small, 8-bit) with one head per question. it reads the command and knows the questions and options it was trained on, which is all the assistant needs.
it trained on 203 requests and kept 17 aside to check itself. about 70 seconds from pressing Train to the downloadable folder being ready, and it cost $0.02.
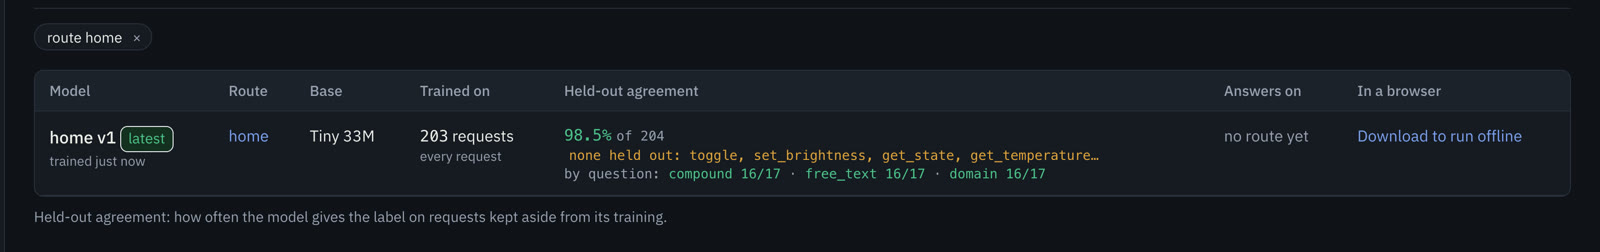
98.5% means it gave the same answer on 201 of the 204 question-answers from those 17 requests it never saw. that number is flattered by easy yes/no questions, and 17 requests is a small check. the page says so too: several actions (toggle, set_brightness, get_state…) weren't in the held-out 17 at all. I treat it as a sanity check and trust what happens in the house more.
5. download it and go offline
"Download to run offline" gives you a zip with the model, its tokenizer, a README with what it knows and how it scored, and serve.py, a small server that answers the same POST /v1/systemone requests jev does.
pip install onnxruntime tokenizers numpy
unzip offline.zip && cd home-v1
python serve.py --host 0.0.0.0then the second url swap: HA-Jev → Reconfigure → address http://<that machine>:8787. I ran the model in a container with no route to the internet at all, so if it answers, it answered on its own.
| I said | Home Assistant | who answered |
|---|---|---|
| turn off the kitchen lights | Turned off the light | the local model |
| turn the kitchen lights back on | Turned on the light | the local model |
| is the kitchen window open | Sorry, I did not understand that | the local model, unsure, so it passed |
a real kitchen-lights request takes about 5 ms round trip to the local server (5.4 ms median over 25 tries, 3 to 14 ms), vs jev's 70 to 130 ms plus the trip to the internet.
the window one didn't work, and I'm glad it didn't guess. the model was 45% sure, HA-Jev wants 60% before it acts, so it passed. it had only seen a handful of "is X open" questions. a few more of those and one more 70 second training should fix it.
what it cost
| jev answering 267 requests while I collected | $0.098 |
| writing 80 commands for the thin answers | $0.002 |
| training Tiny once | $0.02 |
| running it at home | nothing |
all of it came out of the free credit every account starts with.
will it run on a raspberry pi?
probably, but I haven't timed it on one yet. it's plain Python plus onnxruntime, both install on 64-bit Raspberry Pi OS, and at 34 MB and ~5 ms on a laptop there's a lot of headroom.
when this is the wrong tool
if your app is doing search, like picking an emoji out of thousands, a classifier is the wrong shape because there's no fixed set of answers to learn. Max Leiter's embedding approach fits that way better. this works when your app keeps asking the same questions with the same options.
Questions
FAQ
Can I fine-tune Jev itself?
No, TypeSafe doesn't release Jev's weights. You train an open model on the same requests instead.
Do I have to stop using Jev?
No. Keep Jev answering while you collect and switch when your own model is good enough. It's per route and you can switch back.
What else can run offline besides Tiny?
Laya is on the same list. It reads the questions at run time, so it copes with new options without retraining, but it's 842 MB. For a box in a cupboard Tiny is the one.
Does it work in other languages?
Tiny is English only (it's built on an English encoder). For other languages, Laya multilingual (100+ languages, about 640 MB) is coming to the same list.